
Retrieval-augmented generation, usually shortened to RAG, is a way of giving an AI system selected information at the moment it answers a question. Instead of relying only on the knowledge encoded during model training, a RAG application retrieves relevant passages from a defined external collection—such as policies, product documents, manuals or research—and supplies them as context for the response.
That simple distinction matters. A language model can produce fluent text even when it has not seen the current version of a policy or does not know which source a team considers authoritative. Retrieval-augmented generation does not turn a model into a truth machine. It gives a system a more reviewable route to current, scoped information and creates an opportunity to show a reader where an answer came from.
What is retrieval-augmented generation?
The term comes from research published in 2020 by Patrick Lewis and colleagues. Their paper described RAG models that combine a model’s learned, or parametric, memory with a separate non-parametric memory: a dense vector index of Wikipedia accessed through a neural retriever. The point was to improve knowledge-intensive language tasks while addressing difficult problems around updating knowledge and providing provenance.
In practical business use, the external collection is usually narrower than Wikipedia. It might be an approved help center, a product catalog, a set of legal templates, a technical runbook or a controlled set of research reports. When a user asks a question, the system searches that collection for relevant material, passes selected passages to the language model and asks the model to answer with that context in view.
That is different from simply attaching a long document to a chat. A well-designed RAG system has a repeatable pipeline for organizing information, finding relevant passages, enforcing permissions and recording what supported an answer. It is also different from fine-tuning. Fine-tuning changes model behavior or task performance through additional training; RAG typically changes the information available to a response without changing the underlying model’s weights.
How a RAG system works
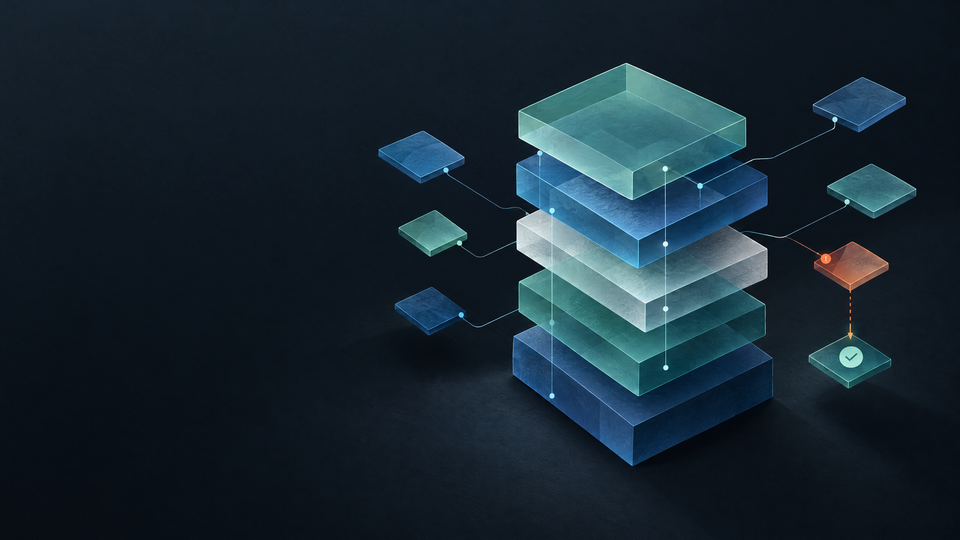
Implementations vary, but the core workflow is usually made of five stages:
- Choose and prepare the source material. A team selects documents that are authoritative for the intended job, records their owner and status, removes duplicates and defines how updates will arrive. The first quality decision is editorial rather than technical: a RAG system cannot retrieve a policy that was never included, and it should not treat an unreviewed collection as an authority.
- Break content into retrievable units. Long material is commonly split into smaller passages, often called chunks. Metadata can retain the document title, section, date, owner, jurisdiction, product version or permission group. Those details help a system return a passage that is not only similar to a query but suitable for the user and the task.
- Represent and index the material. Many RAG systems use embeddings: numerical representations that let software compare the meaning of a query with the meaning of a passage. The original RAG research used a dense vector index. In a production system, this index may be paired with keyword search, filters, reranking or a document store; the implementation is a means, not the goal.
- Retrieve under the right controls. The user’s question is used to find candidate passages. A system should apply permissions and source rules at this stage, not merely conceal a sensitive answer after the fact. The selected context is then added to the model’s instructions or prompt.
- Generate, cite and observe. The model drafts an answer from the supplied context and its trained capabilities. A useful experience gives the user links or citations back to the source passages, makes uncertainty visible and records the retrieval set for later review. The answer is the end of one interaction, not the end of quality control.
Amazon Web Services describes the same broad pattern in its RAG explainer: external data is prepared, represented numerically, retrieved for a relevant query and added to the prompt before generation. The architecture can be useful because teams can update the external collection as policies or product information change, rather than asking a base model to somehow know a newly published document.
Where RAG helps—and where it does not
RAG is a good fit when the useful answer depends on a bounded collection of sources that changes over time. Examples include an internal assistant that helps employees find the current travel policy, a support tool that drafts answers from approved product documentation, or a research interface that points readers back to the reports behind a summary. In each case, the system’s value comes from the choice and upkeep of the source collection as much as from the model’s prose.
It is less suitable as a shortcut around unresolved decisions. A messy archive full of conflicting, obsolete or unowned documents will not become reliable merely because it has been embedded. Nor does retrieval make a model competent to decide sensitive outcomes. If a workflow can affect a person’s access, finances, health, legal position or employment, the organization still needs domain review, a clear authority model and a meaningful human decision point.
RAG also should not be confused with a generic web search. A web search is often broad and exploratory. A RAG collection is normally curated for a defined task and can carry metadata, access rules and version information. The narrower design can be a strength: it helps a team explain why a source was eligible for use. It can also be a weakness if the collection becomes incomplete or stale. Scope needs active management.
Why citations and permissions are core features
A citation beside an AI answer is useful only if it points to the material that actually supports the claim. Teams should test whether the cited passage is relevant, whether important claims are fully supported and whether the answer overstates what the source says. If a system retrieves a policy from the wrong country, an outdated revision or a neighboring team’s restricted folder, a polished response can still be operationally wrong.
Security requires the same discipline. OWASP warns that weaknesses in vectors and embeddings can affect RAG applications through data poisoning, manipulated outputs and access to sensitive information. Its guidance recommends fine-grained access controls, permission-aware stores, validation of knowledge sources and detailed retrieval logs. In other words, a retrieval layer is not a neutral library shelf. It is a route by which data can influence an AI response and, in some systems, later actions.
Use permission-aware retrieval from the start. A person should not receive a passage merely because it is semantically similar to a question; they should receive it only if they were entitled to access it before the model saw it. Treat external documents as content to be assessed, not as instructions that gain authority simply because they were retrieved. And preserve enough trace information to answer a basic operational question later: which sources were selected, for whom and why?
How to evaluate a RAG system before broad release
Begin with one narrow question set and a reviewed corpus. For each test, record the expected source or acceptable sources, the answer that is supported, the information that must not appear and the escalation condition. Include routine questions, ambiguous wording, stale documents, conflicting sources, missing information and requests from users with different permissions.
Then evaluate both layers. The retrieval layer should return relevant, authorized and current material. The generation layer should accurately use that material, distinguish evidence from inference and avoid filling gaps with confident speculation. A response can fail even when the underlying search worked: it may omit a condition, combine two incompatible passages or cite a document that does not support its conclusion. It can also fail when the prose is excellent but the retriever reached the wrong source.
The same operational habits that matter for AI agents matter here: define the job, document allowed data and actions, test realistic cases and inspect the path as well as the final answer. For that broader discipline, see Unhyd’s guide to testing AI agents before scale. For foundational context on the model that writes the final response, Unhyd’s large language model explainer is a useful companion.
A practical starting checklist
- Pick a single recurring question type with a clear owner and reversible outcome.
- Use a small, reviewed source collection with document owners, dates and update rules.
- Preserve document metadata and make access rules part of retrieval, not an afterthought.
- Require source links or citations where an answer depends on evidence.
- Test normal, incomplete, conflicting, stale and adversarial content before expanding use.
- Log the source set, permission decision and response so errors can be investigated.
- Keep high-impact decisions with a responsible person, even when RAG is used to prepare the work.
Retrieval-augmented generation is best understood as a design pattern for connecting language models to a controlled body of information. Its promise is not that software can replace judgment. Its promise is that a system can answer from information a team has selected, maintained and made reviewable. Whether that promise holds depends on the sources, permissions, evaluation and human accountability around the model.
FAQ
Does RAG train the language model?
Usually, no. RAG generally retrieves external material at answer time and includes it as context. Fine-tuning is a separate process that changes a model through additional training.
Can RAG eliminate hallucinations?
No. Retrieval can give a model better context, but it cannot guarantee that the retrieved source is current, that the model will interpret it correctly or that every claim in the response is supported. Test retrieval and generation separately.
Is a vector database required for RAG?
Not in every implementation. Vector search is common because it can retrieve semantically related passages, but systems may combine it with keyword search, filters, reranking and traditional document stores.
What is the safest first RAG use case?
Start with a narrow, read-oriented workflow that uses a reviewed source set and produces a draft or cited answer. Add broader data access or consequential actions only after the system has been evaluated in the actual workflow.